

Contact WebRAY
-
 Clearer AI Usage
Gain full visibility into the cost-effectiveness of AI usage across departments and individuals: which models are used, by whom, and how well they perform. Usage across the entire company, every department, every group, and every user is visible on a single dashboard. Multi-dimensional usage statistics and analytics by department, user, model, and application put an end to the "AI compute black box."
-
 More Efficient AI Usage
Generate prompt analysis reports by department and user, with effectiveness scoring, turning individual experience into enterprise assets. Intelligent model routing automatically selects the right model based on task type and sensitivity level, with automatic failover to a backup model if the primary model becomes unavailable. Semantic caching reuses results for identical or similar queries, reducing token consumption and improving response times.
-
 More Secure AI Usage
Provide unified access and hybrid scheduling for mainstream LLMs and privately deployed models. A unified access channel for LLMs including DeepSeek, Tongyi, Zhipu, and Kimi, and is compatible with mainstream LLM API protocols. Proprietary models can be deployed on-premises, keeping core data within the organization's boundary, with support for hybrid public-private scheduling. A built-in four-layer AI security guardrail framework protects AI usage comprehensively, from ingress to egress and from data to behavior.


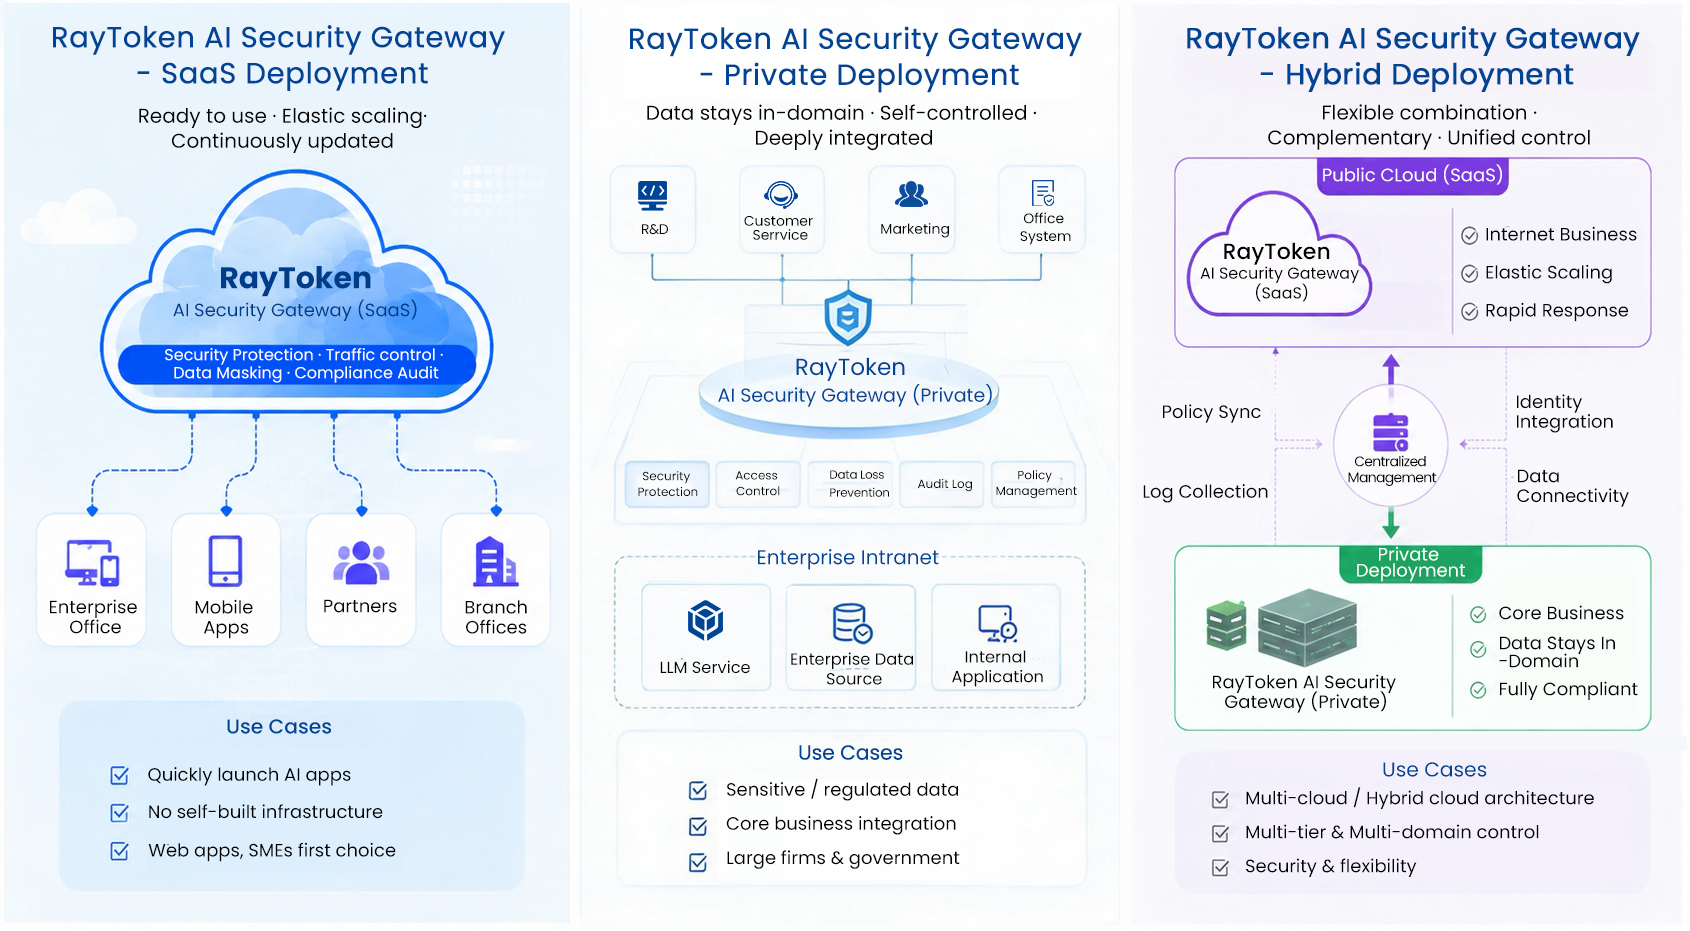
SaaS Deployment
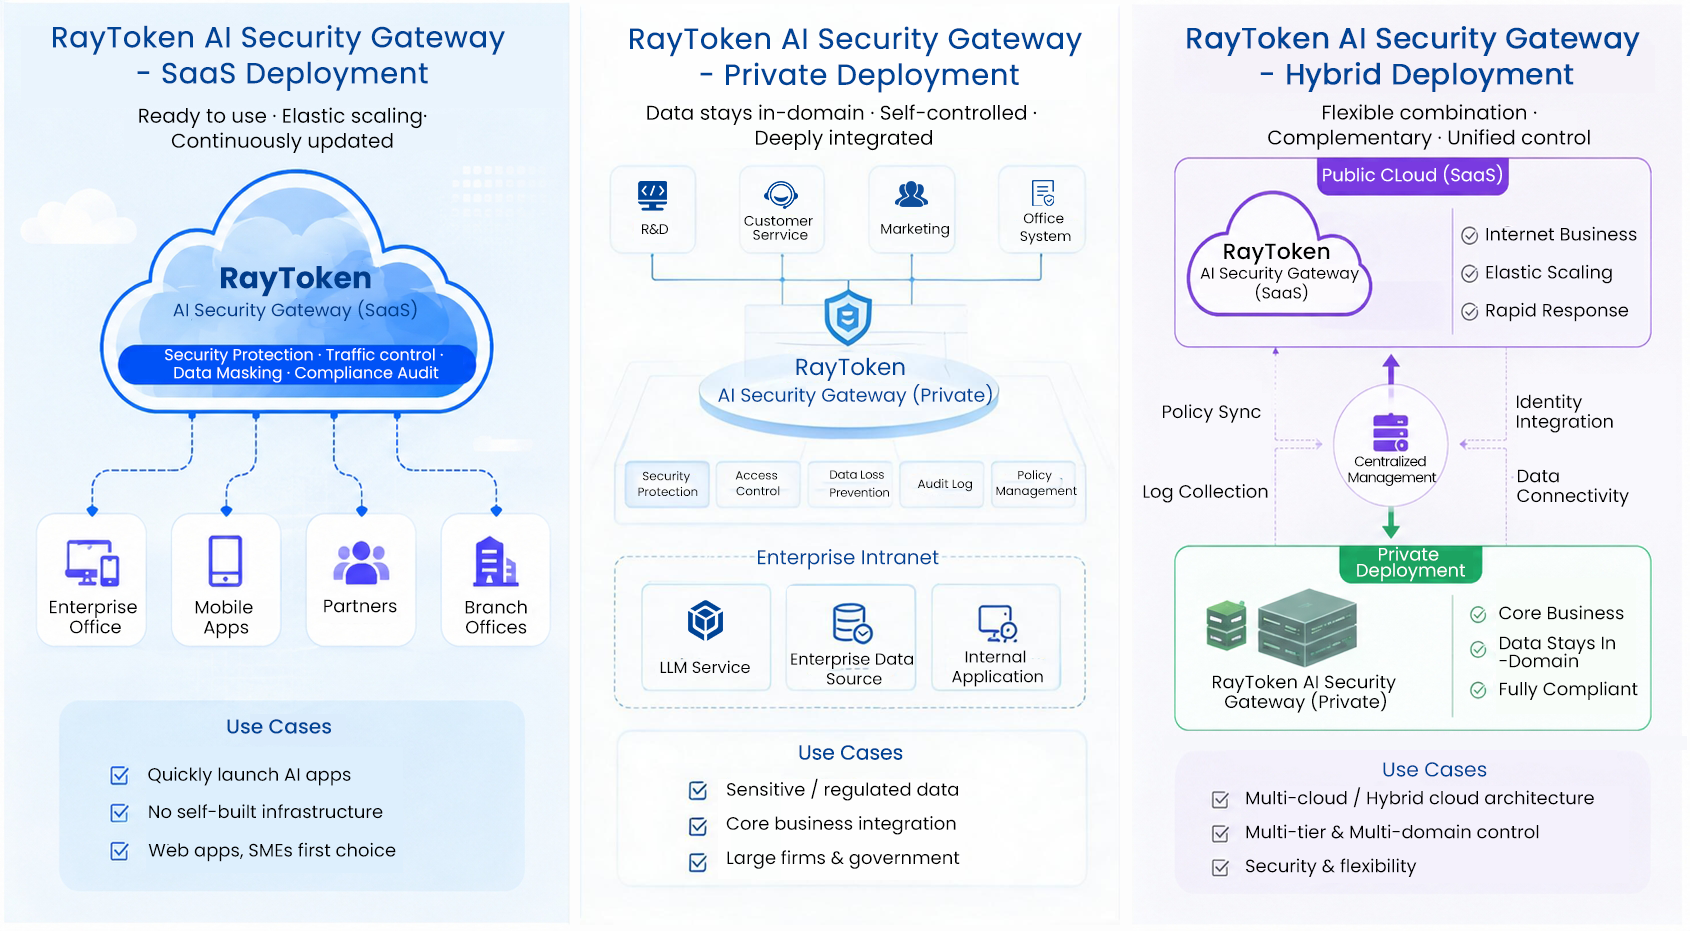
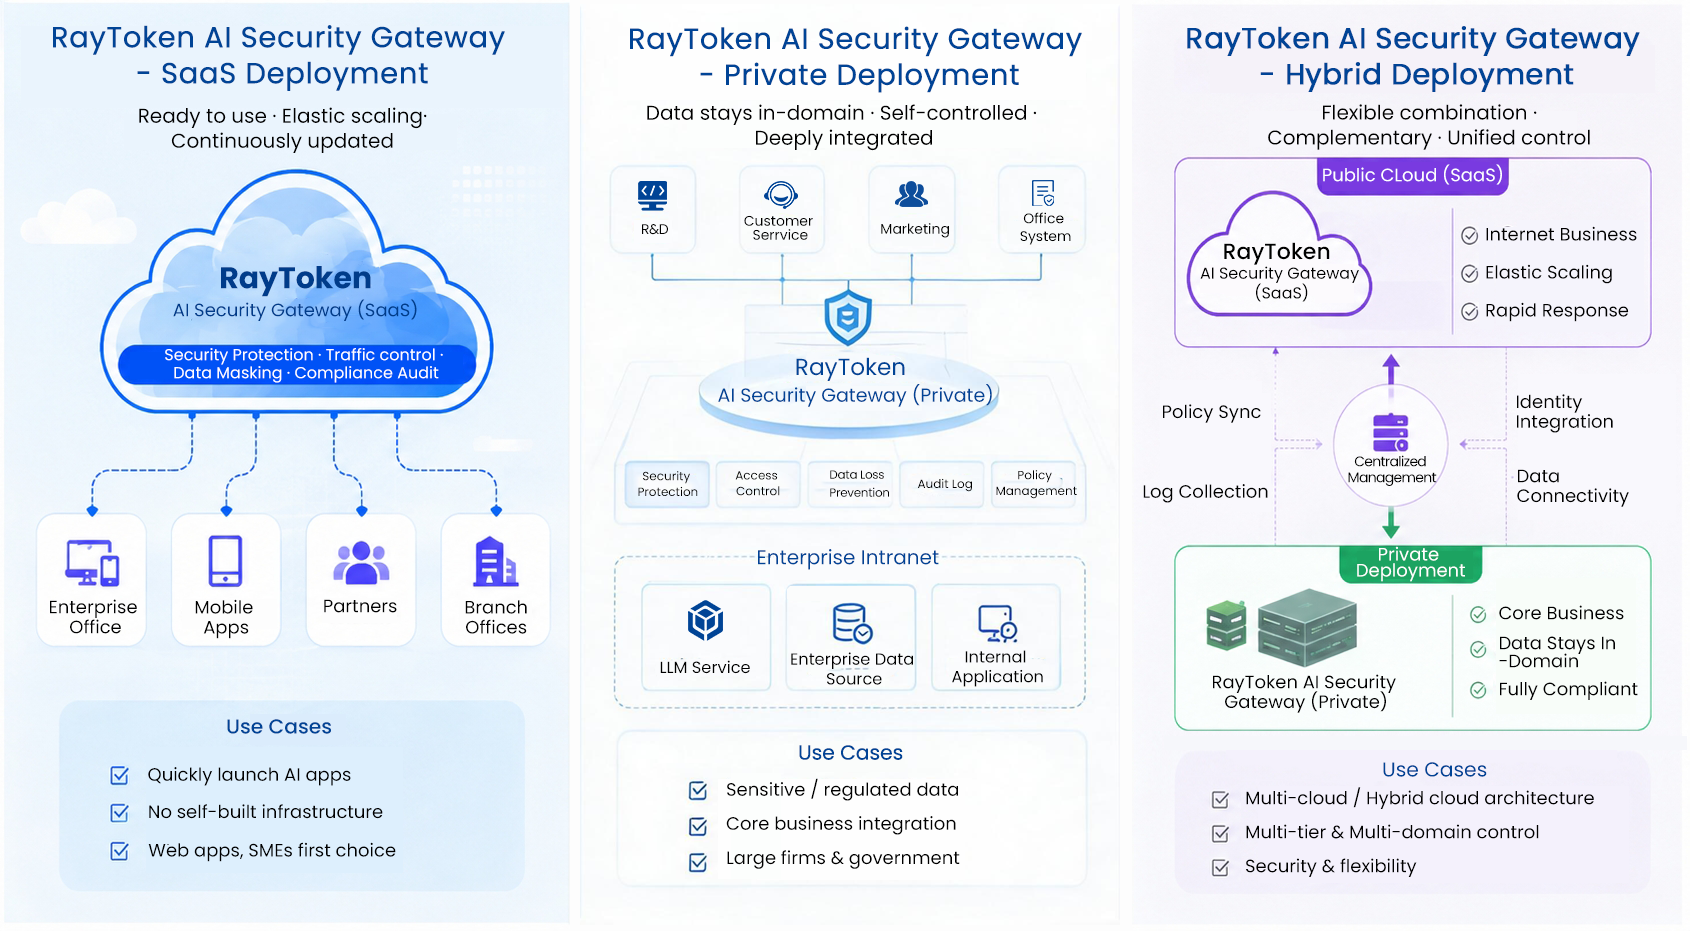
Provide one-stop cloud-based access with no need for in-house computing infrastructure. Get started in minutes and access 300+ mainstream LLMs through a unified API. Supports elastic scaling and continuous integration of the latest models.
Hybrid Deployment
Support leading domestic models such as DeepSeek, Qwen, and GLM, with one-click model switching to meet diverse business needs. Keeps 100% of inference processing and data within the enterprise intranet, meeting MLPS Level 3 and industry compliance requirements.
Private Deployment
Supports a hybrid “SaaS + private deployment” model, allowing enterprises to choose based on data sensitivity. Sensitive business data is processed by privately deployed models and stays within the enterprise intranet, while general office tasks use SaaS services to benefit from continuously updated model capabilities.